Positron AI Secures Atlas and Titan Inference System Orders from General Compute
General Compute will deploy Positron’s Atlas systems in the first quarter of 2027 and has committed to purchasing its next-generation Titan platform, expanding cloud inference capacity with memory-focused accelerators designed to reduce costs and reliance on high-bandwidth memory.
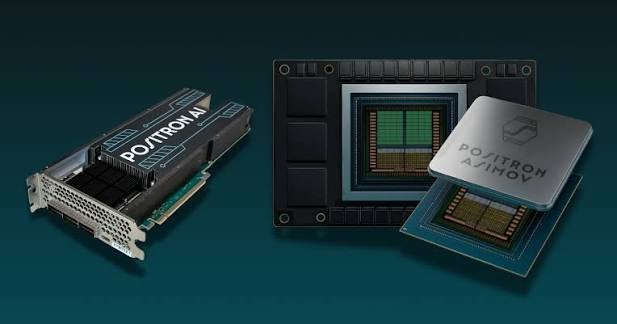
Positron AI announced that General Compute will purchase its Atlas inference systems and has committed to purchasing its next-generation Titan systems, expanding General Compute's dedicated inference offering. The agreement expands General Compute's world-class inference offering with Atlas and establishes a path to Titan, Positron's next-generation memory-first platform designed to bring larger models with the highest interactivity serving and better economics to customers at scale.
The partnership combines General Compute's infrastructure capabilities with Positron's experience deploying and integrating Atlas at hyperscaler scale. Positron is deploying Atlas with customers including Oracle Cloud Infrastructure (OCI). That work encompasses networking and security validation, rack integration, power and cooling constraints, and operation within established infrastructure environments. General Compute's planned Atlas deployment brings that practical experience to another cloud provider, connecting Positron's inference architecture with the requirements of delivering capacity to customers at scale.
"Inference demand is exploding, and the frontier has moved to models with trillions of parameters that have to respond in real time," said Mitesh Agrawal, CEO of Positron AI. "Titan is built for that moment, designed to deliver the highest levels of interactivity at an order of magnitude better throughput per dollar on multi-trillion-parameter frontier models than any solution on the market today. With Atlas, we are proving out General Compute's heterogeneous compute thesis right now, deploying quickly alongside the infrastructure they already run. And because Positron's architecture is uniquely memory-first, we can support a build-out at massive scale without waiting on the scarce HBM supply that is holding back the rest of the industry."
As AI applications become more interactive and agents perform longer sequences of tasks, response time affects how quickly the entire workflow can progress. Infrastructure providers must deliver that responsiveness while managing throughput and cost. Positron's memory-first approach addresses a central constraint in token generation: moving model data to the processor quickly enough, while keeping model weights and growing context in memory. By designing memory bandwidth, capacity and compute together, Positron targets more useful inference per dollar and per watt at the response speeds these workloads require.
General Compute will use Atlas to expand the inference infrastructure options available to its customers in Q1 2027. The deployment will draw on Positron's experience integrating Atlas alongside existing NVIDIA infrastructure and within established data center environments.
"Our mission is to deliver the best neocloud that includes GPUs and alternative chips under one roof. Deliberately pairing AI use cases with optimal architecture and chips for the tasks they need. All under one contract and set of SLAs for our customers," said Finn Puklowski, co-founder and CEO of General Compute. "Positron AI's architecture is a game-changer for rapidly speeding up tokens and inference. Adding Atlas and Titan to our racks delivers this for our customers."
General Compute's commitment to Titan extends the relationship from current Atlas systems to Positron's next-generation inference platform. Powered by Asimov, Positron's custom inference silicon, Titan is designed to combine multi-terabyte memory capacity with the bandwidth needed for responsive token generation. Its LPDDR-based architecture is designed to keep larger models and longer context in memory, reducing reliance on storage offload. For these memory-intensive workloads, Positron is targeting improved performance and lower total cost of ownership than GPU-only configurations.
The Atlas deployment lays the foundation for heterogeneous, disaggregated inference, matching different stages of a workload to the hardware best suited to them. That approach pairs GPUs for compute-intensive prompt processing with Positron's memory-first accelerators for token generation, creating a path to Titan's larger-model capacity and targeted performance and cost advantages.